amberlin-trainstation
Where the model behind Amberlin's tool calling is chosen and measured. The current phase trains nothing, on purpose: a small model under a grammar already scores 114 of 119 held-out questions.
- Status
- Measuring; training only if it is needed
- Licence
- Apache-2.0
- Built with
- LoRAONNXPythonSGLang
- Part of
- Amberlin AI
- Source
- amberlin-trainstation
When Amberlin needs a fact, her language model has to pick the right tool and fill in the call correctly, or know that no tool is needed. trainstation is where that is measured, on a held-out set of questions the model never saw while its setup was being tuned.
Before touching any weights, it takes tool calling as far as two cheap levers go: the catalogue of tools the model is shown, and the tools themselves, with a grammar underneath that holds the output to a valid call. With a corrected system prompt and a merged file-search tool, Ministral 3 3B scores 114 of the 119 held-out questions: it picks the right tool for 98 of the 103 that need one, and makes no call for all 16 that need none. The 8B scores 117. Getting every argument right is harder: the 3B fills in the required ones correctly for 87 of the 103.
A grammar fixes the form of a call, never the judgement behind it: with the catalogue offered, the right-tool rate is the same with the grammar on or off. Training comes later, and only if a measurement on this project’s own data says it helps.
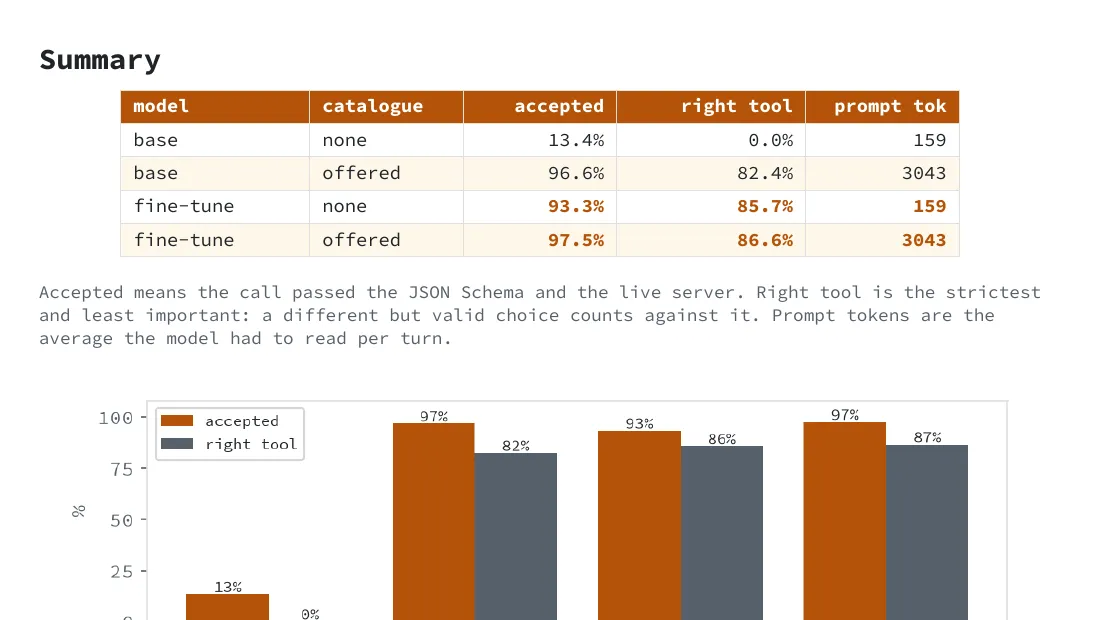
The training pipeline is already in place: dataset, LoRA, merge, export to ONNX and evaluation. An earlier fine-tune of a Qwen model went through it, and its report is the picture above; it was measured on a different split, so its figures do not compare with these.
Install
Not a package: trainstation is the workbench where the models in the catalogue are chosen and measured.